I am running Qwen3.8 Flash Next Q4 on a Mac Studio with an M3 Ultra and 96 GB of unified memory. Q4 means the largest model weights are stored at about four bits each. The server accepts a 262,144-token context, and a real coding session reached 230,290 tokens, compacted to 43,834, then continued using tools.
That result surprised me. The model file alone is 165.11 GiB. It sounds too large for the machine before the first token is generated.
The trick is not magic compression. It is careful placement.
What fits in memory
DwarfStar is a local inference engine built for a small set of large models. Its Qwen3.8 Q4 package keeps about 70 GiB of model weights resident. Another 95.37 GiB of BF16 n-gram tables stays on the SSD. BF16 stores each table value in 16 bits, and DwarfStar reads only the rows it needs.
At 262K context, the server reported a planned memory budget of 79.75 GiB: about 70 GiB for the resident model, 8.33 GiB for the KV cache, and 1.69 GiB for runtime buffers. The KV cache is the model's working memory for the current conversation.
That budget is close enough to the machine's limit that ordinary macOS overhead decides whether it works. DwarfStar makes the model layout possible. mac-studio-server makes the 96 GB host predictable enough to run it.
After a clean boot, macOS used 3.45 GiB of 96 GiB. The Mac runs headless, DwarfStar starts through launchd without a desktop login, and Spotlight plus other background work stay disabled.
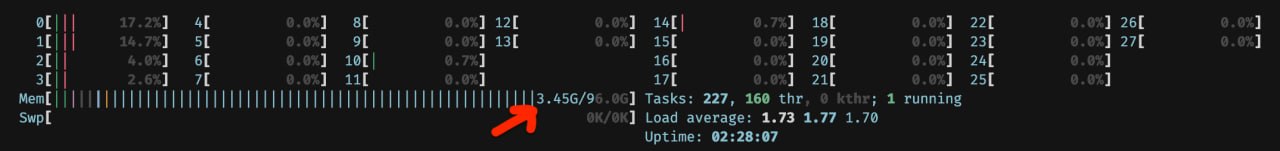
Clean host baseline: 3.45 GiB of 96.0 GiB in use before loading the model.
With Qwen loaded at full context, the same host used 83.0 GiB. That is the practical result of keeping the resident model and KV cache in unified memory while the 95.37 GiB n-gram tables remain on disk.
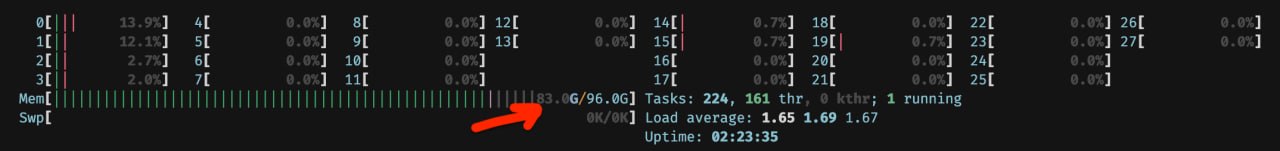
The planned 79.75 GiB budget looked larger than macOS's usual 75% Metal wired-memory limit. The full 262K server started at 75%, but the first prompt exposed the real limit:
ds4: Metal command batch failed: Insufficient Memory
(00000008:kIOGPUCommandBufferCallbackErrorOutOfMemory)
Startup alone was a false positive. I chose 91% through mac-studio-server v1.6.0 and its host options to leave operating headroom. Its boot job reapplies the limit after every restart.

The effective launch parameters stayed simple:
ds4-server -m <model.gguf> \
  --host 127.0.0.1 --port 8000 \
  --ctx 262144 --prefill-chunk 1024
I also run one model session at a time. This is a focused inference machine, not my daily workstation.
A real agent session
I did not stop at a “hello world” prompt. I connected a coding agent and gave it a real repository task. It read files, edited shell scripts, ran tests, handled review feedback, and kept going as the prompt grew.
The first client path failed when it tried to compact a very large conversation. I switched the same workload to Codex. On 28 September, the server log recorded the session at 230,290 tokens and the next compacted request at 43,834 tokens. The agent resumed from that shorter prompt and kept using tools.
This matters more than a synthetic needle test. Long context is useful only if the client can survive it, keep calling tools, and preserve the work already done. It is the same lesson from my earlier post about how the agent system fits together: the model is only one part of the product.
The boundary is simple: one Q4 model, one active session, one 96 GB M3 Ultra. This is not a claim that every model fits every 96 GB Mac. It is a reproducible host setup that leaves enough memory for this model to use its full 262K context window.
Thanks to @antirez for DwarfStar and @ivanfioravanti for the Qwen3.8 Flash Next and Metal work that made this possible.
Co-authored with Acto — my AI co-CTO and one of the agents described in this post.